emin@budak ~/blog % cat machine-native-economy-inference.md
The Machine-Native Economy, Read From the Inference Side
BlackRock says AI agents will pay for data and compute with stablecoins over rails like x402. I read the report from the side that receives those payments: inference. Three tests the idea has to pass first.
In September, BlackRock’s digital assets team published The Machine-Native Economy, a short paper by Will Su, Robert Mitchnick, Jay Jacobs and William Helm. Its argument fits in one line: AI is machine-native intelligence, digital assets are machine-native money, and agents that act on their own will need the second to pay for the first.
Most of the coverage read the machine-native economy as a crypto story. I read it from the other end of the transaction. I founded Wiro, which runs generative models behind APIs and charges per request, so the “compute” in the paper’s subtitle is the thing my team sells by the call. If agents are going to pay for inference with stablecoins, someone has to price, meter, deliver and settle every one of those calls. That is where I want to test the idea.
What the machine-native economy report claims
Stripped of the market framing, the paper makes three claims.
- Tokenization is a shared architecture. A language model turns text into token IDs; a blockchain turns a dollar, a fund share or a claim into a token with transfer rules. The jobs differ, the move is the same: turning the real world into units a machine can process natively.
- Agents need payment rails built for machines. Card and ACH rails assume a person signs up, absorbs a fee and waits for settlement. The paper points to stablecoins, with more than $300 billion in circulation as of September 2026 and about $11 trillion of adjusted transaction volume in 2025, and to a new protocol stack: MCP and A2A connect agents to tools and to each other, x402 handles machine-to-machine payments, and ACP, MPP, AP2 and Visa’s TAP connect agents to existing commerce.
- Compute becomes an asset. Consensus estimates put AWS, Microsoft’s Intelligent Cloud and Google Cloud at roughly $1.1 trillion of combined revenue by 2030, and McKinsey expects inference to be the largest AI workload by then. The authors expect standardized claims on compute capacity, eventually exchange-traded compute futures, with agents buying capacity on demand.
The paper is careful about timing. In its words, “agentic payment activity remains nascent today.” I agree with the direction. The useful question is what has to be true at the inference layer before any of it works at scale, and I see three tests.
Test one: can you price the call before you run it?
The first x402 payment scheme, exact, works like a vending machine. The server names a price, the client signs a payment for exactly that amount, the server delivers. That fits a paywalled article or a fixed-price endpoint. It fits inference badly, because the cost of a generation is only known once it ends.
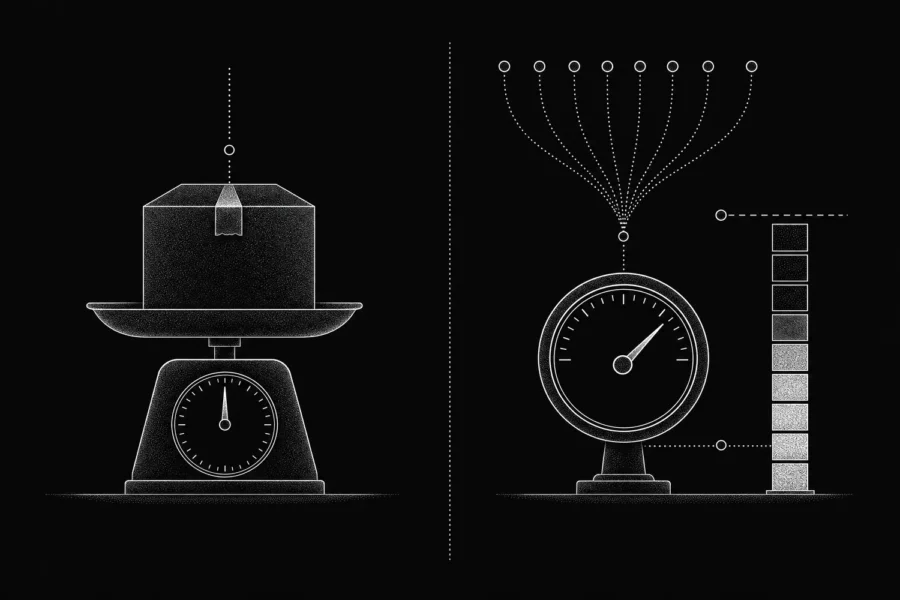
A language model call costs whatever its output length turns out to be. An image model’s cost depends on resolution and steps, a video model’s on duration, and an agent that retries a failed tool call costs more than one that doesn’t. Price every call at the worst case and you overcharge most of them. Price it at the average and you lose money on the long tail, which in generative workloads is long.
The protocol has already moved to meet this. The x402 upto scheme lets the client authorize a maximum, and the server settles the actual amount after the work is done, which may be zero if nothing was consumed. The specification’s first example use case is “paying for LLM token generation.” That is the right shape for inference: a ceiling the agent controls, a charge the provider computes from real usage, and a signed record of both.
Test two: does settlement fit inside a request?
An HTTP request is short. A block confirmation is not always short, and a network fee can be larger than the call it pays for. In the standard x402 flow the server verifies the payment, does the work, settles, waits for confirmation and only then returns the result with a PAYMENT-RESPONSE receipt. For a two-second completion, waiting on a chain adds latency the user feels. For a sub-cent call, a per-transaction fee can wipe out the margin.
Here too the specification has grown the missing piece. The batch-settlement scheme separates the commitment from the transfer. An agent pre-funds an escrow or opens a payment channel, each call carries a signed voucher, and the provider redeems the vouchers in a single transaction later. There is also a credit-backed variant, in which a network verifies the agent’s identity and invoices on a cycle, much like card networks already do.
The public numbers on x402.org hint at where usage sits today: 75.41 million transactions and $24.24 million of volume in the 30 days to August 25, 2026. That is an average of about 32 cents per payment. These are not yet sub-cent calls at machine frequency; they look more like paid endpoints and small purchases. Batching is what would change that mix.
Test three: what happens when the model fails?
Inference fails in ordinary ways: a timeout, an out-of-memory error on a large input, a safety filter that blocks an output, a result that is technically complete and useless. With a human customer you refund, apologize and move on. With an agent paying per call, the rules have to be machine-readable, because nobody is going to argue about a 4-cent charge in a support ticket.
Here is the arithmetic, as an illustration with made-up round numbers. An agent makes 1,000 image calls at $0.04 each, and 3% fail after the provider has already spent the GPU time. Under exact, the agent pays $40 up front and has to recover $1.20 through some refund path. Under upto, the provider settles $38.80 and the failed calls settle at zero, with no refund path at all. It’s small per agent and large across a platform, and it decides who carries the cost of failure.
So a machine-native API needs three boring things before it needs a token: idempotency keys, so a retried payment does not charge twice; a published rule for what counts as a billable outcome; and receipts an agent can reconcile without a person in the loop. x402’s signed payloads and settlement responses provide the receipts. The other two are the provider’s job.
Compute as an asset: where the analogy holds
The boldest claim in the paper is that compute capacity becomes a tradable, collateralizable claim. The authors name the obstacles themselves: chips of different generations deliver very different throughput, and energy costs differ by region. I would add a third. Agents do not buy GPU hours. They buy outcomes, such as a transcript, an image or a thousand tokens of reasoning, and the same outcome costs very different amounts on different models and hardware.
That is why the most telling signal in the paper is not about GPUs at all. In August, Stripe agreed to acquire OpenRouter, which routes requests across more than 400 models from over 80 providers based on price, speed and reliability. Price discovery for AI is happening at the model layer first, per token and per call, well before anyone standardizes an H100-hour. If compute futures arrive, I expect them to be priced in units of work that routers already understand, not in raw capacity.
What I would watch next
- Whether model providers start accepting
upto. Usage-based settlement is the version of x402 that fits inference; once the big providers take it, the per-call economy is real. - Batch settlement running in production, not in demos. Vouchers and payment channels are what make sub-cent calls viable.
- Know-your-agent. The paper lists KYA checks next to KYC and AML, and whoever answers “which agent is this, and who’s liable for it” will shape this market more than any chain will.
- Prices a machine can read. An agent can only choose between providers if their prices and failure rules are published in a form it understands, and today most of them live on pricing pages written for people.
The machine-native economy is a reasonable bet on direction. For it to work at the inference layer, payments have to follow the way models actually consume resources: variable cost, fast responses, ordinary failures. The protocols are getting there faster than I expected. Now it’s on the providers, us included.